Related Topics:
Build High Performance Server-
How to solve the high temperature problem in network server rack rooms
The ideal server room temperature is between 68°F and 77°F. Go much higher, and you risk overheating. Using a thermostat or sensor can help you monitor and control this. It protects your equipment and helps keep your business running. This comprehensive guide will walk you through why server room overheating is a. Learn how server rack cooling prevents overheating, boosts performance, and ensures reliability with expert tips and advanced solutions.
[PDF Version]
-
How many years can an AI server room server be used
Amazon Web Services now says its servers have a 'useful life” of five years, while Google and Microsoft expect servers to last for four years. Let's look at the timeline of how Tech companies extended the Server life and estimated savings: January 2020, AWS extended theirs from 3. Modern data center GPUs used for AI workloads typically last only 1-3 years—far shorter than their consumer counterparts due to extreme operating conditions. Office servers are rated for 20-25°C with clean air. Use industrial-grade hardware rated ASHRAE Class A3/A4 (up to 45°C), or build an. This is where AI server clusters stand out, crafted for HPC (High-Performance Computing), enormous amounts of data, and very demanding AI workloads. Some of these operations involve deep learning, image recognition, and natural language processing. From running large language models to perfecting. Whether it's advanced analytics, real-time decision-making, or custom AI applications — the need for AI-ready infrastructure is reaching the on-site server rooms of mid-sized and enterprise companies.
[PDF Version]
-
How many cards does an AI server typically have
AI servers typically incorporate multiple accelerator cards such as GPUs and TPUs. These chips feature an enormous number of pins and extremely high signal transmission rates. Therefore, motherboards and accelerator cards require ultra-high-layer PCBs with 20 or even 30+ layers, along with HDI. The DGX A100 resembles a typical home computer and can be divided into five main hardware modules: Fan Module: Located at the front, the fan module consists of eight fans, which align with the standard 8U configuration found in traditional servers. Hard Drives: Positioned below the front fan. With six NVSwitch units on an A100-based system, the per-system value is RMB 1,170. High-Core CPUs Used to manage tasks and coordinate GPU workloads. Below, we round up the best GPU server configurations for your AI tasks. Most GPU servers have a CPU-based motherboard with GPU based modules/cards mounted on that motherboard. This setup lets you select. The Software Reference Architecture is comprised of individually optimized NVIDIA-Certified System servers that follow a prescriptive design pattern to ensure optimal performance when deployed in a cluster environment.
[PDF Version]
-
FC Adapter Low Noise and Performance Comparison How to Choose a Performance-Specific Adapter
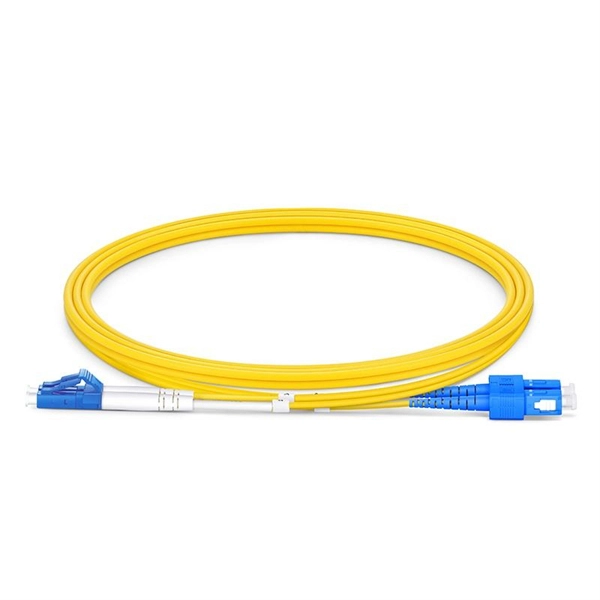
This guide explores the different types of FC adapters, their polishing styles, and how they perform in real-world scenarios. FC adapters are designed for applications that demand high stability and durability, particularly in. Your Guide to Fiber Optic Adapters and Mismatch Pitfalls Have you ever found yourself holding an SC patch cable and suddenly realized your device only has LC ports? Or maybe you plugged in what appeared to be the correct type of connector to your device, only to notice the network performance going. FC adapters are key components in fiber optic communication systems. Unlike RF connectors that transmit electrical signals, fiber optic connectors use light signals, allowing for high-speed and long-distance. FC Connector: FC connectors are threaded connectors that use a screw-on mechanism. FC connectors are known for their excellent stability and repeatability.
[PDF Version]
-
Designing server lag AI
This guide provides insights into the necessary bandwidth, latency, and scalability requirements to prepare your network for the AI era. AI and machine learning (ML) applications are bandwidth-intensive and require low latency for real-time processing and insights. A custom AI server flips the script, giving you ownership over your infrastructure and the freedom to innovate without compromise. In this overview, Jun Yamog guides you through the essentials of building a high-performance AI server, from selecting the right GPUs to optimizing thermal management. When people talk about AI or LLMs, it often sounds as if any such workload automatically requires a data center, a rack full of GPUs, and a massive budget. In kilowatts alone, the increase in power density is enormous: traditional data. Any delay in data retrieval directly affects key AI performance metrics: Prefill Time: The delay before token generation starts. Time to First Token (TTFT): The time before an AI model begins responding. Browse examples below for inspiration, then make your own viral content. Type your server lag video concept or paste a script.
[PDF Version]
-
Airport AI Server OSFP
6T optical modules, and with a roadmap toward 3. 2T, OSFP meets the massive data throughput required by GPU clusters and AI accelerators. Its larger form factor supports advanced cooling and airflow, making it ideal for sustained high-power workloads in. Designed for 800G and 1. The current AI training clusters need network bandwidth that exceeds the capabilities that existed five years earlier. 6T for high-bandwidth systems, while the OSFP cage and connector provide a 112Gb/s, high-density interconnect with excellent signal integrity and thermal performance. It delivers up to 800Gbps bandwidth per port using advanced 224G SerDes and PAM4 modulation, enabling ultra-low latency communication between thousands of. According to TrendForce, 800G transceiver shipments are projected to explode from 24 million units in 2025 to 63 million in 2026 — a 162% year-over-year surge driven almost entirely by AI infrastructure buildouts. Dell'Oro Group notes that 800G reached 20 million ports in just three years, compared. In an AI cluster, one flaky optical link can turn your training run into a very expensive nap. Breakout AI Optimization:.
[PDF Version]
-
AI inference server AMD
AMD has announced the Instinct MI350P, a PCIe accelerator aimed at enterprises that want on-premises AI inference without rebuilding their data center. The card is a dual-slot, full-height, full-length design built for standard air-cooled servers. Deploy small and mid-size models on AMD EPYC™ 9005 server CPUs—on prem or in the cloud—and help maximize value from your computing investments. As the industry shifts from training models to running them, CPUs can pull double duty: run AI and general-purpose workloads side by side. It is also the first time in nearly four years that. Many organizations face tradeoffs between cloud-based inference and the cost of upgrading on-prem systems to support large accelerator platforms. You no longer need to write custom logic with the Vitis AI Runtime libraries for each XModel. AMD posted strong first-quarter results, with surging demand for AI infrastructure pushing data center revenue up 57% year over year and cementing the segment as the. The AMD Inference Server is an open-source tool to deploy your machine learning models and make them accessible to clients for inference. For all these models and hardware.
[PDF Version]
-
AI Server Sector Analysis
Market Size by Server, by Hardware, by Cooling Technology, by Deployment, by Application, by End Use. A comprehensive report by Global Market Insights Inc. The market is expected to grow from USD 167. 89 Billion by 2035 with a CAGR of 27.
[PDF Version]
-
How much space is ideal for a network server rack
Typical spacing is 10-20% of equipment height. Export your results to CSV for documentation or share the configuration with your team for planning purposes. Businesses must consider a variety of factors when selecting the right server rack size to fit their needs. With this reality in mind, keep reading for a guide to server rack sizes, including why server. Understanding server rack sizes is essential for data centers, enterprise IT teams, and businesses deploying high-performance infrastructure. The right rack dimensions ensure optimal equipment compatibility, airflow efficiency, cable management, and long-term scalability. This calculator helps you plan rack layouts by calculating the total rack units. A rack unit (abbreviated as U, less often as RU) is a standardized unit of measurement used to describe the height of equipment designed to be mounted in a 19 or 23-inch-wide server rack.
[PDF Version]